Introduction
What is LegoFlow?
Coding is a core capability of modern LLMs, yet producing high-quality coding data remains surprisingly complex. The pipeline spans multiple platforms, sandboxes, and compute resources, with substantial human effort required at every step. LegoFlow is an easy-to-use and interactive framework that lets users operate this pipeline end to end through a coding agent. It is part of the LegoX family.
Highlights
-
Agent-native workflows: LegoFlow exposes repository and PR collection, task verification, trajectory rollout, training, evaluation, and live dashboards as plugin skills that coding agents can trigger.
-
Broad coverage: LegoFlow supports 8+ programming languages, 20+ task tags, and trajectory rollouts across Claude Code, OpenCode, and OpenHands.
-
Open-source dataset: We release LegoFlow-SWE, built from more than 12M PRs and containing 5,000 verified tasks with 9,767 rollouts, including 2,780 successful trajectories. With only 1K training samples,
Qwen3.5-35B-A3Breaches 70.2% on SWE-bench Verified, 48.8% on SWE-bench Pro, and 57.0% on SWE-bench Multilingual. -
End-to-end iteration: LegoFlow allows an agent to run the full loop without human intervention, from PR collection and task verification to trajectory rollout, model training, and evaluation. In one run, this process improved
Qwen3.5-35B-A3B-Basefrom 7.6% to 64.4% on SWE-bench Verified. See the end-to-end run.
System Design
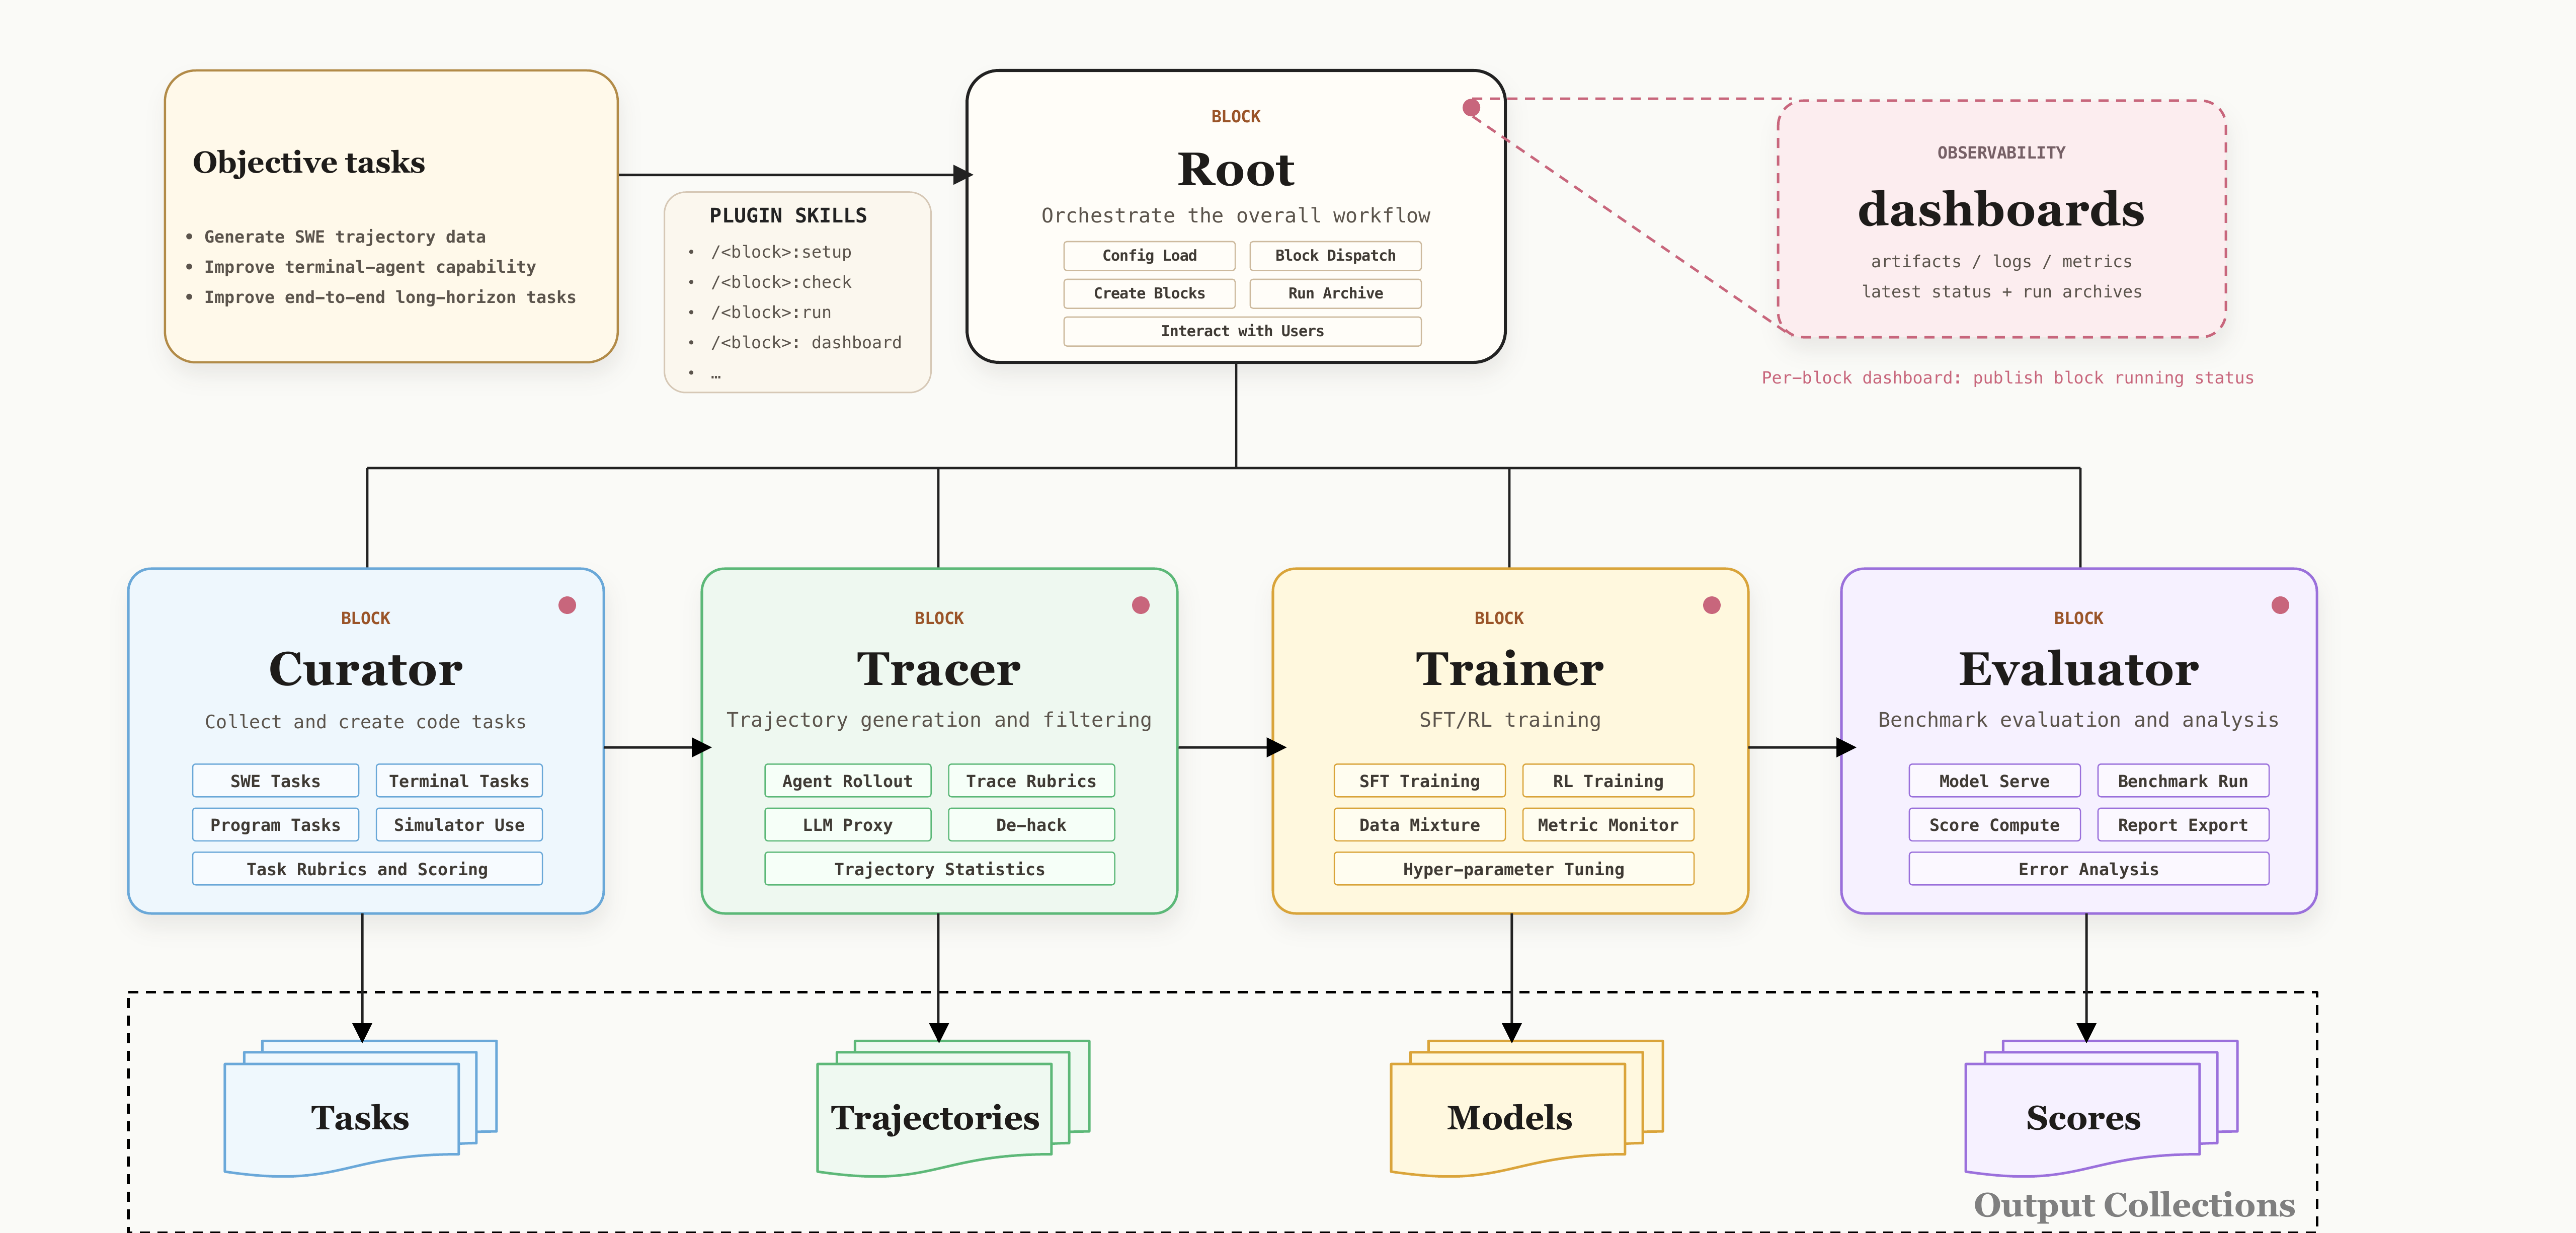
The overall data pipeline is organized as a tree of blocks. A block is a contract for agentic workflows and one runnable unit in the pipeline. Each block owns its config, scripts, plugin skills, artifacts, dashboard, and pinned repository dependencies. The root block orchestrates four child blocks:
- Curator: curates high-quality SWE and coding tasks from GitHub PRs, issues, and online forums.
- Tracer: collects high-quality trajectories with verified rewards, supporting rollouts across multiple coding scaffolds such as Claude Code, OpenCode, OpenHands, and Terminus.
- Trainer: converts rollout traces into training-ready formats and launches end-to-end training workflows.
- Evaluator: measures checkpoints on coding benchmarks, with rubric- and tag-level analysis.
Why Blocks?
Blocks make the pipeline easier to use and easier to change. Because every stage follows the same contract, users can operate the whole system through plugin skills, restart a failed stage from its archived state, swap one block without breaking the others, and inspect artifacts through consistent dashboards. This keeps the workflow approachable for general users while leaving room for advanced analysis and new agent-data domains. See What is a Block for the exact block anatomy and how the diagram maps onto the repository structure.
Start by Use Case
| I want to... | Go to |
|---|---|
| Understand why this exists at all | Motivation |
| Install it and run something | Getting Started |
| Build verified SWE tasks from GitHub | Curator |
| Collect agent trajectories on tasks I already have | Tracer |
| Fine-tune a model on trajectories | Trainer |
| Benchmark a model or a checkpoint | Evaluator |
| Add a block of my own | Adding New Blocks |